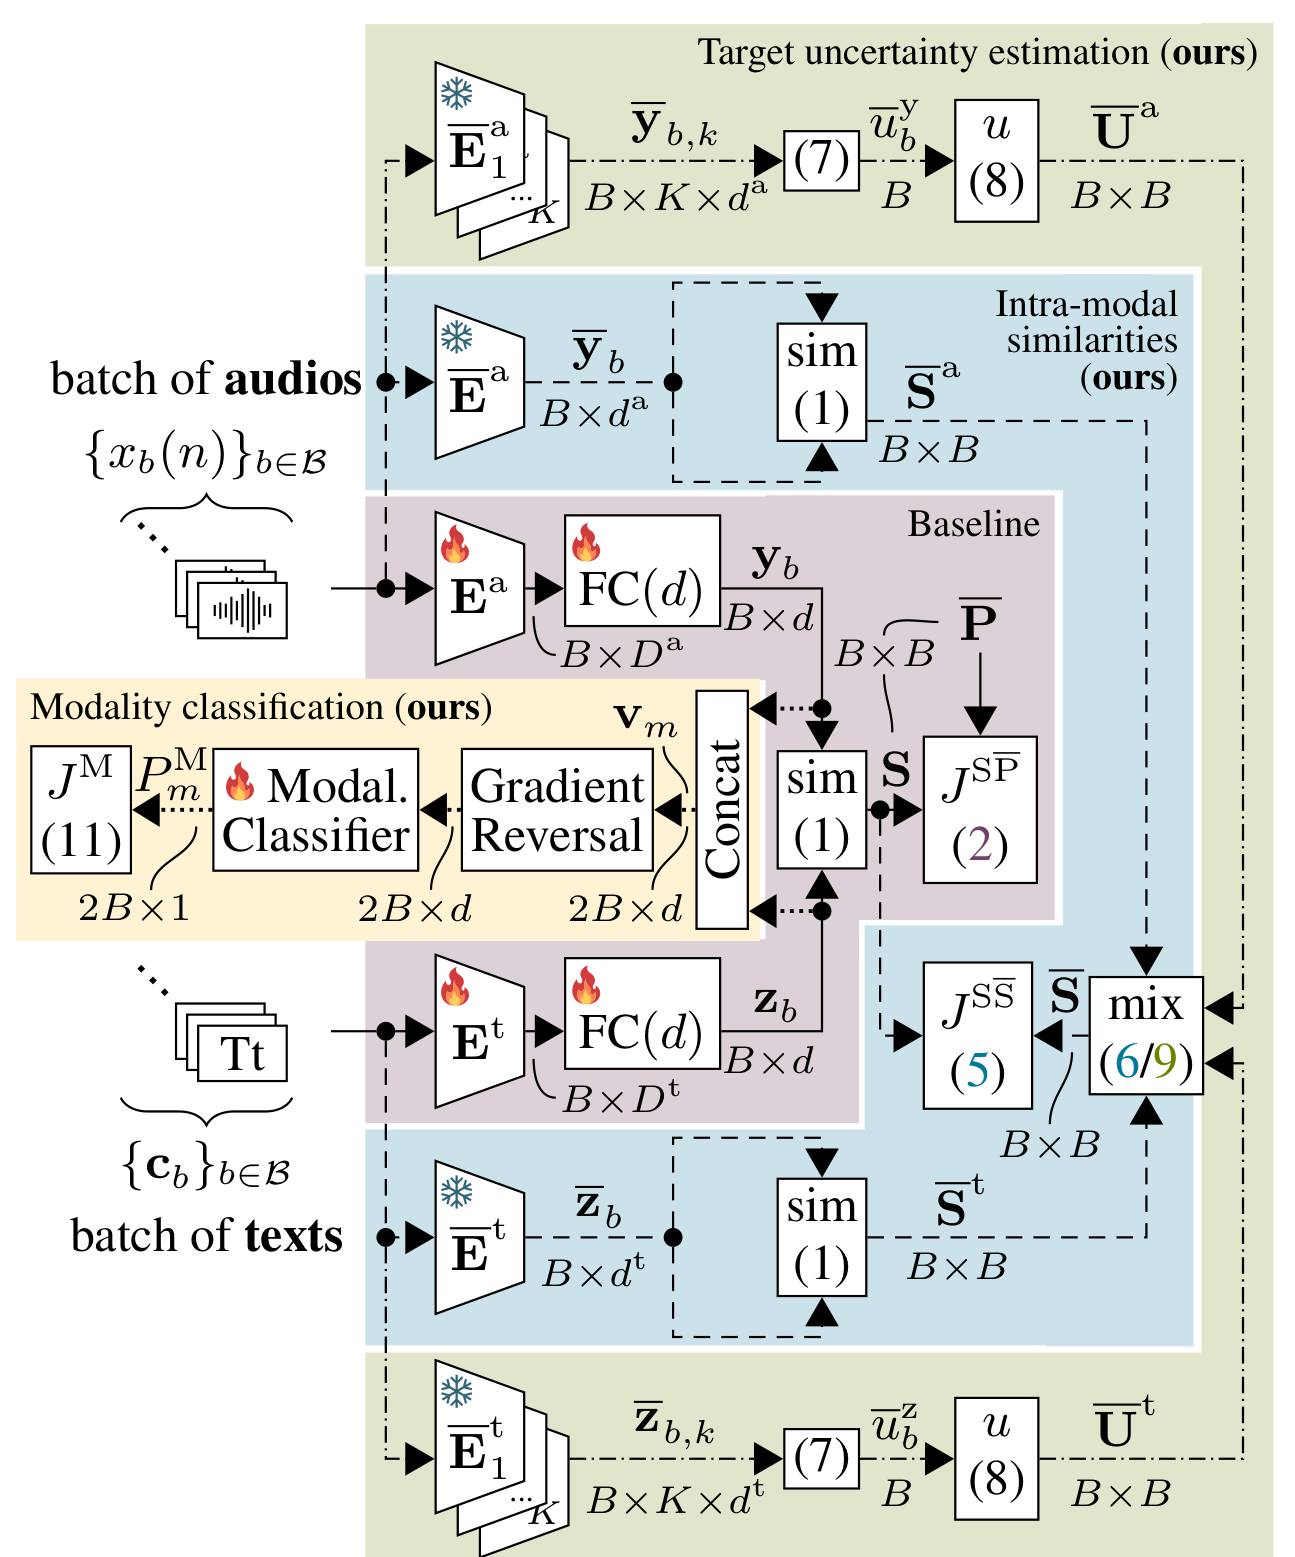
Contrastive inter-modal representation learning is powerful in zero-shot classification, text-queried audio retrieval, and audio-queried text retrieval. Recently, image-text contrastive learning has been proposed with soft labels generated from text-text similarities between all samples in a batch. As our first contribution, we use such intra-modal text-text similarities as inter-modal text-audio similarity targets. Second, we generalize this to also gain information from audio-audio similarities. Third, we propose a method to obtain similarity targets from these intra-modal similarities using uncertainty estimation. We further investigate additionally employing a modality classification branch and using MSE-guided estimation. Finally, in a specified training regime, we show that our methods are competitive with SOTA on a number of downstream tasks, while using only a fraction of training data and batch size. Our utilized training data and pre-trained models are publicly available.
@inproceedings{vonaspern2026,
  title     = {{Leveraging Mutual Intra-Modal Similarity Supervision for Text and Audio}},
  author    = {von Aspern, Julian Miguel and Defraene, Bruno and Vafeiadis, Anastasios
               and Kutscher, Oleksiy and Seidel, Ernst and Fingscheidt, Tim},
  booktitle = {Proc. of Interspeech},
  year      = {2026},
  month = sep,
  address = {Sydney, Australia},
  pages     = {1292--1296},
  doi       = {10.21437/Interspeech.2026-3300},
}